

 Contact Us


 Home /
Robot Fleet Business Continuity: How to Plan for Robot, Dock, Network, and Software Failures

Humanoid Robot Hand Dexterity Verification: Grasp Set, Tool Use, Force Control, and Recovery
Oct 08, 2026

Industrial Exoskeleton Fit and Sizing: Anthropometry, Adjustment Time, PPE, and Shared-Device Programs
Oct 08, 2026

Robot Duty Cycle and Thermal Limits: Why Rated Payload and Speed Do Not Guarantee Continuous Operation
Oct 08, 2026

Robot IP Ratings Explained: What IP54, IP65, and IP67 Do — and Do Not — Prove
Oct 08, 2026
Robot Fleet Business Continuity: How to Plan for Robot, Dock, Network, and Software Failures
A robot stops working. The dock cannot charge it. The network drops. The fleet management software crashes. Any one of these events can halt part or all of a robot fleet — and the question is not whether they will happen, but what happens to your operations when they do.
Most robot procurement discussions focus on selecting the right product, negotiating the right warranty, and defining the right service-level agreement. These are necessary steps. But they all assume that when something breaks, the supplier will fix it within an agreed timeframe. Business continuity planning (BCP) asks a different question: while you are waiting for the fix — whether that takes hours or days — how do you keep operations running?
This article breaks robot fleet failures into four dimensions — robot body, dock/charging station, network, and software/system — and for each dimension describes failure characteristics, operational impact, mitigation strategies, and recovery paths. It also maps the cascade paths between these dimensions, because a single failure rarely stays single for long.
Why Robot Fleet BCP Differs from General Business Continuity
ISO 22301:2019 ("Security and resilience — Business continuity management systems — Requirements") provides a general framework for business continuity: conduct a business impact analysis, assess risks, define a continuity strategy, build the plan, and test it. The standard applies to organizations of all types and sizes and is not specific to robot fleets. However, its methodology — particularly the emphasis on identifying critical functions and defining recovery objectives — is a useful starting point for fleet operators.
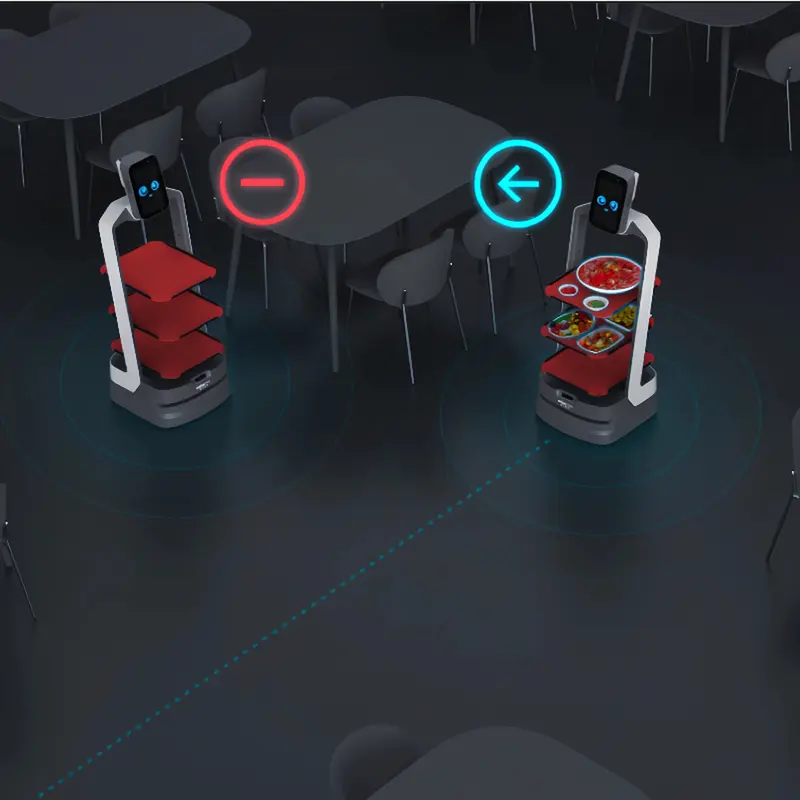
What makes robot fleet BCP different from general IT or facility continuity planning is the interdependence of physical and digital systems. A robot is not just a machine that breaks; it is a node in a network that depends on docks for energy, on software for task allocation, and on network infrastructure for communication. When one node fails, the impact propagates through the system in ways that are not always obvious.
Consider a common scenario: a charging dock fails. The immediate consequence is that one charging position is unavailable. But if the fleet has been sized with minimal dock redundancy, the remaining docks now serve more robots, charging queues lengthen, effective working hours per robot drop, and throughput declines — not because any robot broke, but because the energy infrastructure could not redistribute the load. This is the kind of cascade that a BCP must anticipate.
The framework presented here is not a substitute for ISO 22301 or for a formal BCP developed with qualified specialists. It is a robot fleet-specific lens that helps operations managers, facility managers, and IT-OT coordinators identify where single points of failure exist and what to do about them.
The Four Failure Dimensions
Robot fleet failures can be grouped into four dimensions. Each has distinct failure characteristics, impact patterns, mitigation options, and recovery paths. The dimensions are not independent — cascade paths between them are mapped in the next section.
Robot Body Failures
Failure characteristics. Robot body failures encompass sensor faults (noise, bias drift, complete signal loss), actuator faults (motor stoppage, joint seizure, restricted range of motion), end effector faults (gripper malfunction, insufficient grip force), and power system degradation (battery capacity loss, voltage drops). Research on robot failure modes — based on studies focused on service robot environments; applicability to industrial robot fleets should be confirmed against specific product configurations — categorizes these into sudden failures (complete component loss) and progressive failures (gradual performance decline that may go unnoticed until a threshold is crossed).
Impact. A single robot body failure typically removes one unit from the fleet. The operational impact depends on fleet sizing — if the fleet was sized with no spare capacity, losing one robot directly reduces throughput. If the fleet includes redundancy (a spare ratio built into the fleet sizing calculation), the remaining robots may absorb the workload, though cycle times may increase.
Mitigation. Key strategies include:
- Building spare capacity into the fleet sizing (e.g., sizing for 110% of peak demand so that losing one robot does not drop throughput below requirement)
- Automatic fault detection and isolation, so that a failing robot removes itself from the fleet rather than blocking a path or causing a collision
- Graceful degradation: the fleet management system redistributes tasks among remaining robots rather than halting the entire operation
Recovery path. On-site repair → spare part replacement (if critical spares are available) → robot recommissioning and rejoining the fleet. The recovery time depends on spare parts availability, technician response time, and the complexity of recommissioning (some robots require recalibration after hardware replacement).
Dock and Charging Station Failures
Failure characteristics. Dock failures include charging contact degradation (pitted or worn contacts), dock power supply faults, docking alignment failures (the robot cannot physically connect to the dock), and dock communication faults (the dock cannot report status to the fleet manager). Some of these are mechanical wear issues; others are electrical or firmware-related.
Impact. A single dock failure removes one charging position. If the fleet operates with N docks for N robots (no spare dock), losing one dock creates a bottleneck: the robot assigned to that dock must find another, charging queues form, and effective working hours decline. The impact is often gradual rather than immediate — robots do not stop instantly when a dock fails; they run on battery until depleted, creating a delayed but cumulative throughput loss.
Mitigation. Key strategies include:
- Dock redundancy (N+1 or more charging positions relative to the number of robots)
- Dock health monitoring (tracking contact resistance, charging current stability, and docking success rates to detect degradation before failure)
- Manual charging fallback (a procedure for operators to manually connect robots to chargers if automated docking fails)
- Dynamic charging strategy adjustment (prioritizing low-battery robots for available docks)
Recovery path. On-site inspection → dock module replacement or contact cleaning → recommissioning. Dock recovery is often faster than robot body recovery because docks are simpler devices, but spare docks or dock modules should be stocked if the facility operates multiple units of the same type.
Network Failures
Failure characteristics. Network failures include WiFi coverage gaps (dead zones where robots lose connection), network congestion (bandwidth saturation causing packet loss and latency), switch or router hardware faults, and configuration errors (incorrect VLAN tagging, IP conflicts, firewall rules blocking fleet traffic).
Impact. The impact of a network failure depends heavily on the fleet architecture:
- In centralized architectures (common in traditional AGV systems), the central controller dispatches tasks and routes to all units. If the network link between the controller and the fleet is lost, the entire fleet may stop — the controller cannot send new tasks, and robots that complete their current task have no next assignment.
- In decentralized architectures (common in AMR systems), robots may be able to communicate peer-to-peer and make local decisions, depending on system design. A network failure may prevent new task assignments but may not halt robots already executing tasks — they can continue to their current destination and, depending on the system design, negotiate with peers locally.
Mitigation. Key strategies include:
- Network redundancy (dual WiFi networks, wired-plus-wireless hybrid infrastructure)
- Edge computing capability (robots that can make local decisions when disconnected from the central system)
- Network monitoring with automatic failover to backup infrastructure
- Manual dispatch fallback (operators can directly assign tasks to robots via a local interface)
Recovery path. Network fault isolation → repair or failover to backup network → fleet manager re-establishes connections with all robots → task flow resumes. Recovery time depends on whether the failure is a single access point (fast) or a core switch (potentially long if no redundant core exists).
Software and System Failures
Failure characteristics. Software failures include fleet management system crashes, database corruption or lockup, task scheduling algorithm anomalies (uneven task distribution, path conflicts, deadlocks), and failures introduced by software updates (regressions, compatibility breaks, configuration drift).
Impact. A fleet management software crash can prevent all robots from receiving new tasks. The severity depends on architecture: in centralized systems, a fleet manager crash may halt the entire fleet; in decentralized systems, robots may continue executing current tasks but cannot receive new assignments. A scheduling algorithm anomaly may not crash the system but can cause subtle degradation — robots clustering in one area, paths deadlocking, or charging schedules failing to prioritize low-battery units.
Mitigation. Key strategies include:
- Fleet manager redundancy (active-passive or active-active failover, depending on the system's capabilities)
- Software rollback capability (the ability to revert to a previous stable version if an update introduces a fault — this connects to software update and rollback planning)
- Robot local autonomy (robots that can continue basic operations — moving to a safe state, completing a current task, or navigating to a charging dock — without fleet manager direction)
- Software health monitoring (log analysis, heartbeat checks, alerting on abnormal scheduling patterns — this connects to fleet incident management)
Recovery path. Software fault diagnosis → fix or rollback → fleet manager restart → reconnection with all robots → task flow validation and resumption. The recovery path for software failures often involves the supplier or system integrator, which is why the SLA's "resolved" definition and escalation triggers (covered in a separate article) matter for software-related downtime.
Cascade Paths: When One Failure Triggers Another
The four failure dimensions are not independent. A failure in one dimension can trigger or amplify failures in another. Understanding these cascade paths is essential because a BCP that only addresses each dimension in isolation may miss the points where a single failure becomes a multi-system outage.
The table below maps the primary cascade paths identified in this framework. These are illustrative — no real supplier or product claim is represented.
| Cascade Path | Mechanism | What to Block |
|---|---|---|
| Network Failure → Software/System Failure | Network disconnection prevents the fleet manager from communicating with robots. The system may appear to have a software fault when the root cause is network infrastructure. | Network monitoring that distinguishes "network unreachable" from "software unresponsive" to avoid misdiagnosis and unnecessary software restarts. |
| Dock Failure → Robot Body Failure | A failed dock prevents assigned robots from charging. Batteries deplete, and robots shut down — appearing as robot body failures when the root cause is dock infrastructure. | Dock health monitoring that alerts operators before battery depletion occurs, and dynamic charging reassignment so robots are redirected to available docks. |
| Software Failure → Dock Failure | Fleet manager crash stops charging scheduling. Even functional docks cannot be allocated to robots that need them, effectively disabling the charging infrastructure. | Robot-side autonomous docking capability (robots that can navigate to and connect with a known dock without fleet manager instruction) and a manual charging procedure. |
| Robot Body Failure → Network Failure | Multiple simultaneous robot failures can cause abnormal network traffic patterns (retry storms, reconnection floods) that congest the network and affect healthy robots. | Rate limiting on reconnection attempts and network capacity planning that accounts for reconnection traffic spikes, not just steady-state operation. |
The key insight: a BCP must identify these cascade paths and install blocking measures at the critical nodes. Without blocking measures, a single dock failure can cascade into a fleet-wide outage — not because every robot broke, but because the energy infrastructure could not adapt.
How Architecture Changes Your BCP Strategy
The distinction between centralized and decentralized fleet architectures has a direct impact on BCP strategy. This is not a theoretical distinction — it determines which failure modes are single points of failure and which can degrade gracefully.
Centralized architectures (common in traditional AGV systems) typically route task assignment, path planning, and resource allocation through a central controller. The advantage is deterministic behavior and simpler coordination. The BCP implication is that the central controller is a single point of failure: if it goes down — whether due to software crash, network disconnection, or hardware failure — the entire fleet stops. BCP for centralized systems must prioritize controller redundancy (active-passive failover at minimum) and network path redundancy to the controller.
Decentralized architectures (common in AMR systems) may allow robots to communicate peer-to-peer and make local decisions, depending on system design. The advantage is resilience: if the central system is unavailable, robots can continue executing current tasks and may negotiate with peers to complete local objectives. The BCP implication is different: instead of protecting a single controller, the BCP must ensure that each robot has sufficient local autonomy (navigation, obstacle avoidance, docking) to operate independently for a defined period. The risk shifts from "one point fails, everything stops" to "many points degrade slowly, and coordination quality declines over time."
Buyers should confirm the specific architecture of their fleet with the supplier or integrator. The BCP strategy for a centralized AGV system differs materially from that of a decentralized AMR system, and a plan designed for one architecture may provide inadequate protection for the other.
Building Your Fleet BCP — A Practical Framework
The following framework adapts the ISO 22301 methodology (business impact analysis → risk assessment → continuity strategy → plan → test) to robot fleet operations. It is a practical framework, not a formal BCMS — organizations requiring certified compliance should engage qualified business continuity specialists.
Step 1: Define failure semantics for each dimension. Before preparing backup plans, define what "failure" looks like for each of the four dimensions in your specific fleet. What happens when a robot loses a sensor? Does it stop, slow down, or continue with degraded perception? What happens when the fleet manager crashes? Do robots freeze, complete current tasks, or navigate to safe positions? The failure semantics depend on the robot type, product configuration, and system design — and they must be confirmed with the supplier or integrator, not assumed.
Step 2: Conduct a business impact analysis (BIA) for each dimension. For each failure type, estimate the operational impact: how many robots are affected, how long they can operate in degraded mode, and what the throughput loss is per hour of downtime. The BIA should account for cascade paths — a dock failure that eventually causes robot body failures has a larger impact than the dock failure alone.
Step 3: Define recovery objectives. For each failure dimension, define the recovery time objective (how quickly operations must be restored to acceptable levels) and the recovery point objective (what state the system must be in after recovery — e.g., all robots reconnected and tasks resumed, or just critical-path robots operational). These objectives should be realistic given the available resources (spare parts, on-site technicians, manual procedures).
Step 4: Build mitigation and recovery procedures. For each dimension and cascade path, document the specific actions to take. Include:
- Who detects the failure (automated alert, operator observation, scheduled health check)
- Who is notified (shift lead, maintenance team, IT support, supplier)
- What immediate action is taken (redirect robots, switch to backup network, initiate manual procedure)
- What recovery action is taken (repair, replace, rollback, restart)
- Who authorizes the return to normal operations
Step 5: Test the plan. A BCP that has never been tested is a hypothesis. Testing should include:
- Tabletop exercises (walking through failure scenarios with the operations team)
- Controlled failure injection (deliberately disconnecting a dock, killing the fleet manager process, or dropping a network segment — in a controlled environment and during low-risk periods)
- Full simulation (running a shift with one dimension in degraded mode to measure actual throughput impact against the BIA estimates)
The checklist below summarizes the key items to confirm for each failure dimension.
| Checklist Item | Robot Body | Dock | Network | Software |
|---|---|---|---|---|
| Failure semantics defined and confirmed with supplier | ☐ | ☐ | ☐ | ☐ |
| Spare capacity or redundancy in place | ☐ | ☐ | ☐ | ☐ |
| Automated detection and alerting configured | ☐ | ☐ | ☐ | ☐ |
| Manual fallback procedure documented | ☐ | ☐ | ☐ | ☐ |
| Recovery path defined with assigned owner | ☐ | ☐ | ☐ | ☐ |
| Cascade path to other dimensions identified and blocked | ☐ | ☐ | ☐ | ☐ |
| Tested in tabletop or controlled exercise | ☐ | ☐ | ☐ | ☐ |
What Buyers Should Confirm Before and After Deployment
Before deployment. During procurement and system design, buyers should confirm:
- How the fleet management system behaves when individual components fail — does a robot stop, navigate to a safe position, or continue with degraded capability? This behavior is a product design characteristic and should be documented by the supplier.
- Whether the fleet architecture is centralized or decentralized, and what the supplier's recommended redundancy configuration is for the controller, network, and docks.
- What the supplier's response time is for each failure type (this connects to SLA definitions) and what the buyer is expected to handle independently.
- Whether robots can autonomously dock and charge if the fleet manager is unavailable — this is a critical capability for surviving software and network failures.
- What spare parts should be stocked on-site for the most common failure modes (this connects to spare parts planning).
After deployment. Once the fleet is operational, buyers should verify:
- That automated failure detection actually triggers alerts (test it — do not assume the monitoring works because the supplier configured it)
- That the manual fallback procedures are feasible within the actual facility layout (can an operator physically reach a dock to perform manual charging? Is the manual dispatch interface accessible during a network outage?)
- That cascade paths behave as predicted (a controlled failure test may reveal that a dock failure causes a different cascade than the BIA assumed)
- That the BCP is updated when the fleet changes — adding robots, changing layouts, or updating software can alter failure semantics and cascade paths
Map the gaps in your fleet recovery plan
Tell us your robot and dock setup, network dependencies and critical tasks. We can
coordinate supplier documentation on failure behavior and available recovery
options.
Source List
- ISO 22301:2019 "Security and resilience — Business continuity management systems — Requirements" — ISO official page — https://www.iso.org/standard/75106.html — Current edition (second edition, 2019); general business continuity standard, not specific to robot fleets.
- "Failing Gracefully: Mitigating Impact of Inevitable Robot Failures" — arXiv preprint (accepted to ICRA 2026; not yet published in proceedings) — https://arxiv.org/abs/2608.05313 — Failure mode taxonomy from robotics research; study focused on service robot environments; applicability to industrial robot fleets should be confirmed against specific product configurations.
- Adlemo, A. and Andreasson, S.-A. (1994) "Communication Protocols and Failure Semantics in Intelligent Manufacturing Systems" — IEEE International Conference on Robotics and Automation, 1994 — DOI: 10.1109/ROBOT.1994.351039 — Established in manufacturing systems research; failure semantics concept applied as BCP methodology foundation.
Share on Social:


Contact Us
In This Article
Humanoid Robot Hand Dexterity Verification: Grasp Set, Tool Use, Force Control, and Recovery
Oct 08, 2026
Industrial Exoskeleton Fit and Sizing: Anthropometry, Adjustment Time, PPE, and Shared-Device Programs
Oct 08, 2026
Robot Duty Cycle and Thermal Limits: Why Rated Payload and Speed Do Not Guarantee Continuous Operation
Oct 08, 2026
Robot IP Ratings Explained: What IP54, IP65, and IP67 Do — and Do Not — Prove
Oct 08, 2026